The AI Value Realisation Index
A demand-side lens on the AI bubble debate: how much of the AI value enterprises expect can be verified as real, measured results.
What this measures
The AI Value Realisation Index is a single score from 0 to 100. It measures how much of the AI value that large companies claim can be verified in what they disclose. It is an aggregate across the AI deployers in the S&P 500 and FTSE 100, meaning companies that use AI in their own business. It excludes the AI value chain, which is the chipmakers and the sellers of AI models, platforms and software, along with hybrids like Apple and Amazon. For those companies selling AI is the business, so whether they create value by using AI is a different question. Each company is scored on its own, and the index combines those scores. The score falls into four bands: Talking (0 to 20), Emerging (20 to 40), Proven (40 to 60), and Realised (60 to 100).
The terms
Ladder Level (0 to 5). How strong one piece of disclosed proof is. Level 0, no disclosed AI proof (the company may still mention AI). Level 1, a stated AI plan or goal - an ambition, target or planned investment, with no result yet; merely mentioning AI is not enough. Level 2, a live deployment with usage, adoption or spend to show for it, but no result. Level 3, the first real, quantified result. Level 4, a result tracked over time - a defined metric, such as cost or margin, that can be followed. Level 5, a broken-out, tracked result - AI value reported as its own KPI or P&L line. It is separated from the rest of the business and reported consistently, quarter after quarter, so an outsider can track the same figure over time. Aspirational claims and future targets sit at Level 1, and pilots are capped at Level 2, so neither counts as proof. Proof is drawn from earnings calls, 8-K releases, primary press and SEC filings, and the strongest evidence usually sits in calls and press rather than 10-Ks. Coverage is the S&P 500, updated quarterly, and the FTSE 100, updated semi-annually, each labelled by its reporting period.
Proven Value (0 to 100). A company's score. We take its best Ladder Level in each of three areas: cost, revenue and customer. We add the three Levels and scale the total to 100. Only Level 3 and above counts. A company has to prove value in more than one area to score highly. This is the only place the three areas are used.
Talk Score (0 to 1). How densely a company raises AI, across its SEC filings (10-K and 10-Q) and earnings calls. We count AI mentions relative to how much the company publishes, and how often AI comes up on its calls. We exclude risk-factor boilerplate, and theme and tag what remains. Those counts are put through a saturating curve that lands every company between 0 and 1. No AI talk scores 0. Heavy AI talk approaches 1, with diminishing returns near the top. The curve is fixed, so scores stay comparable across quarters even as AI language spreads. Talk Score is used only as a weight, in step 2 below.
Substantiation. The ratio of a company's evidenced claims against all AI claims. It is a companion figure. It is not part of the index and it is not a multiplier. It sets the size of each bubble on the Talk versus Proof chart and appears on the rankings tables.
How the index is built
Step 1. Score each company, using the Proven Value rule above.
Step 2. Combine company-level Proven Value scores into one aggregate number. Each company's Proven Value is weighted by its revenue multiplied by its Talk Score. A large company that raises AI constantly counts for more than a small, quiet one. We add up the weighted scores and divide by the total weight. This quarter the result is 13.5, in the Talking band.
Why you can trust it
Every company, filing, earnings call and press claim we read is in the underlying data. If an announcement seems to prove more, look the company up and see how its disclosure scored. If something is missing, tell us and we will weigh it next quarter.
Go deeper: Rankings · Company analysis · AI Claim Finder · About
Index by edition
| Quarter | Index | Status |
|---|
Method log
Every published move of the index and every method change that made it more accurate, on the record.
| Date | Type | Change |
|---|
Subscribe for the latest
Weekly analysis and new index reports the moment they publish.
The Proof Gap: AI talk vs. disclosed proof
Share of companies that disclose a live deployment (Level 2), a quantified result (Level 3), and a tracked result (Level 4), by quarter
Disclosure from company filings, 10-K and 10-Q. Quantified impact and proof levels from earnings calls, 8-K releases and web research.
Talk vs. Proof
AI disclosure volume against disclosed, verified proof. Bubble size shows how little of a company's AI talk is substantiated: bigger means more talk and less proof. Select a sector:
Sources: financial filings, earnings calls, press releases and web search.
The Proof Funnel
How far companies can back their AI talk - the strongest proof each has disclosed, cumulative. This measures evidence, not adoption: a company using AI but not disclosing a usage figure or result sits lower.
Slide or play to watch the funnel evolve. Verified at the latest quarter; auto-extracted floor for history. Sources: filings, earnings calls, press and web search.
What kind of proof?
Every disclosed proof point, grouped by the value domain it proves: cost, revenue or customer. Each bar shows the specific levers within that domain.
AvAI - Augmentation vs Automation Index
NEWA companion index. Is enterprise AI running the task on its own, or helping a person do it better or faster? We tag every disclosed deployment as one or the other.
How it's tagged. We split each disclosed AI deployment two ways: automation when the AI runs a core task end to end, augmentation when it helps a person do it better or faster. The tag is new, and companies rarely disclose enough for a definitive call, so it currently covers 1,410 deployments across two years of earnings calls, 8-Ks and filings.
Proven Value - Rankings
Proven Value (0–100) is the proof Level a company reaches in each of three areas: cost, revenue and customer, summed and scaled to 100. Only realised outcomes count, Level 3 and above. A score of 0 means no realised outcome disclosed. Substantiation is a company's disclosed proof set against how much it claims. A low figure means talk runs ahead of proof. Ranked by Proven Value. Click a company to open its analysis.
Subscribe for the latest
Weekly analysis and new index reports the moment they publish.
Explore what companies claim AI delivers
Build a question from the lenses below. Every figure is a deduplicated, sourced claim drawn from filings, earnings calls and 8-K releases. Pick a unit to see the spread of the numbers.
Is AI a bubble? The data says not yet.
Each quarter Marcus Weldon weighs the latest AI Value Gap results against the scale of AI spending, using Jev, TypeSafe's probabilistic decision model.
Bubble-burst probability
≥30% AI-equity correction and ≥20% capex cut, by end-2027
The other readings
Jev sees real signs of over-investment in AI and gives a 30% fall in AI stocks by end-2027 roughly even odds.
Readings by question and horizon
Probability, %
Each latest reading is the mean of 10 separate Jev runs, with every question asked on its own; ticks show the individual runs.
Reading history
| Quarter | Value Gap Index | Correction ’27 | Capex cut ’27 | Bubble burst ’27 | Failure, 5 yrs |
|---|---|---|---|---|---|
| Q3 2026 | Next reading mid-November, after the Index publishes | ||||
| Q2 2026 | 15.7 | 54.3% | 22.5% | 11.2% | 36.4% |
| Q1 2026 | 13.5 | 55.8% | 24.3% | 12.8% | 40.9% |
What each reading measures
Jev vs. ChatGPT
Ask ChatGPT whether the AI bubble bursts by end-2026 and it says 55–70%, a figure drawn from past technology bubbles and the stories being written about this one. Jev puts it at 4%: it only works from the evidence it is handed, and its numbers moved when that evidence moved - every reading fell once Q2 disclosure improved. Little is public about how Jev was trained, so each number is best read as a direction and a rough order of magnitude.
“When data dominates, classify; when text triumphs, chat.”Marcus Weldon
The Bubble Gauge reports model outputs produced by Marcus Weldon using Jev, with the AI Value Gap as an input. They are not part of the AI Value Gap scoring method, and they refer to the aggregate AI investment cycle, not any named company. The AI Value Gap measures what companies have disclosed about AI, not their actual AI use or value. Nothing here is investment advice.
Insights
Essays and analysis behind the index - published on Substack.

Bubble, bubble, toil and AI trouble? The Value Gap + Jev say ‘Not Yet’
Marcus Weldon puts the AI Value Gap to Jev, TypeSafe's probabilistic decision model: an 11% chance of a bubble burst by end-2027. The analysis is now a standing quarterly feature, the Bubble Gauge tab.
Read on LinkedIn →Open the Bubble Gauge →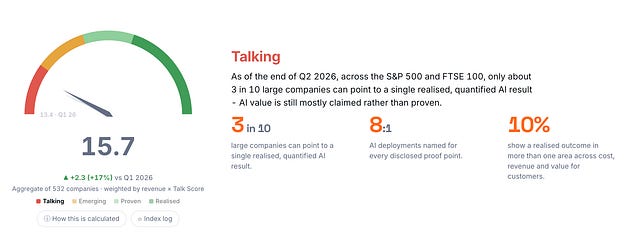
No.44: Q2 Index Update - AI deployment is outpacing proof of value
The Q2 2026 edition closes at 15.7/100, up 17% on the quarter.
Read on Substack →
No.40: The Enterprise AI Value Map
What works, where, how often and how much reaches company economics: evidence from 21,000 AI references across 535 of the world's largest listed companies.
Read on Substack →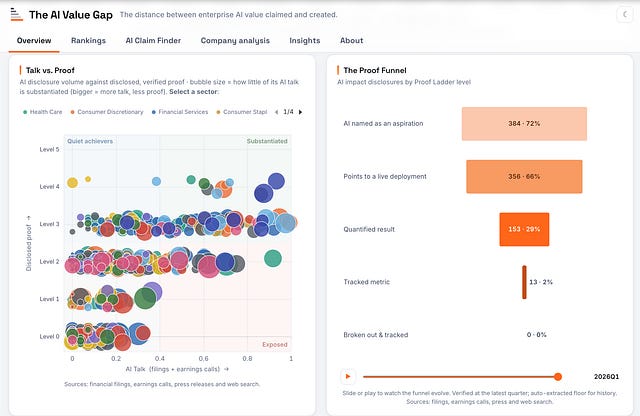
No.35: AI talk is cheap, AI proof is scarce
The market pays no visible premium for companies that can prove AI works. Talk and proof trade at the same price.
Read on Substack →
Q1 2026 AI Swimsuit Report: Talk Dominates
The first quarterly report. The index opens at 13.5/100 - "Talking": across 536 large US and UK companies, only 29% can prove a single realised AI outcome, and claim-by-claim just 8% is backed.
Read on Substack →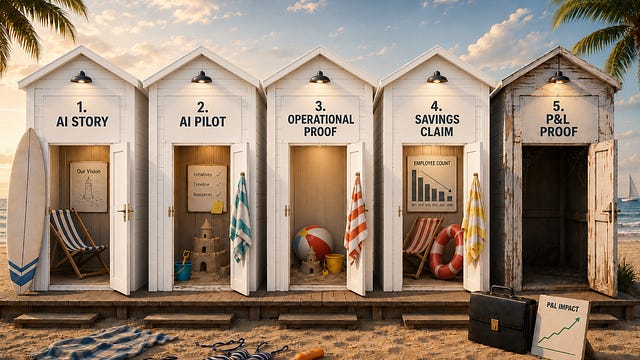
No.33: Introducing the AI Swimsuit Index
A study of S&P 500 companies showing that when the AI tide goes out, only one in five has the financial proof to match the story.
Read on Substack →The AI Value Gap
The distance between enterprise AI value claimed and created.
Why it exists
Every large company now says it is powered by AI, but far fewer can show a hard number that proves it pays.
The whole AI-bubble question turns on that demand-side gap. It comes down to whether enterprises are turning AI spending into real value, and how fast.
Yet almost all of the debate runs on the supply side: hyperscaler capex, chip sales, valuations. Very little measures the value actually landing on the ground.
The AI Value Gap measures that missing side. It tracks verifiable value realisation, company by company, from what those doing the work disclose. The aim is simple: a gauge of where AI value is starting to emerge, and a benchmark for the initiatives large companies are running. For each one it sets what can be proven against what is claimed, and separates the signal from the noise.
"Only when the tide goes out do you discover who's been swimming naked." Our flagship quarterly report's name nods to Warren Buffett: AI is the rising tide, and the Value Realisation Index the measure for when it goes out.
About the author
Amin Mrini
Senior AI operator · Author
Amin Mrini is Chief Commercial AI Officer at a FTSE 50 company, where he leads AI transformation and AI-powered product and customer initiatives across the Group.
He came to AI through strategy and operations leadership, with a career spanning consulting, digital transformation and operating roles in B2B information services, including COO and Chief Digital Officer roles. His work focuses on where AI can create meaningful business value, how products and workflows need to change around it, and how that value can be measured.
Separately, Amin is the author of The AI Value Gap, a weekly publication focused on enterprise AI execution and real-world impact, and the creator of the AI Value Realisation Index, which tracks the gap between corporate AI ambition, deployment and measurable results.
Advisor · Methodology & Framework
Marcus Weldon
Former President, Bell Labs · Former CTO, Nokia
As President of Bell Labs, and Chief Technology Officer of Nokia, Alcatel-Lucent and Lucent Technologies, Marcus built a track record of turning pioneering research into product development and business strategy. He studied chemistry and computer science as an undergraduate before receiving his PhD in physical chemistry from Harvard and joining Bell Labs as a research scientist studying semiconductor surface interactions. His career evolved as he undertook a number of leading technology innovation roles over 20 years in the telecom sector, before founding his own technology consulting company. He recently served as the Neil Armstrong Visiting Professor at Purdue, lecturing on AI, and is currently the Newsweek senior contributing editor for AI. But he spends the majority of his time acting as an AI advisor to pioneering companies and organisations, including working with Amin on the AI Value Gap's methodology and scoring framework.